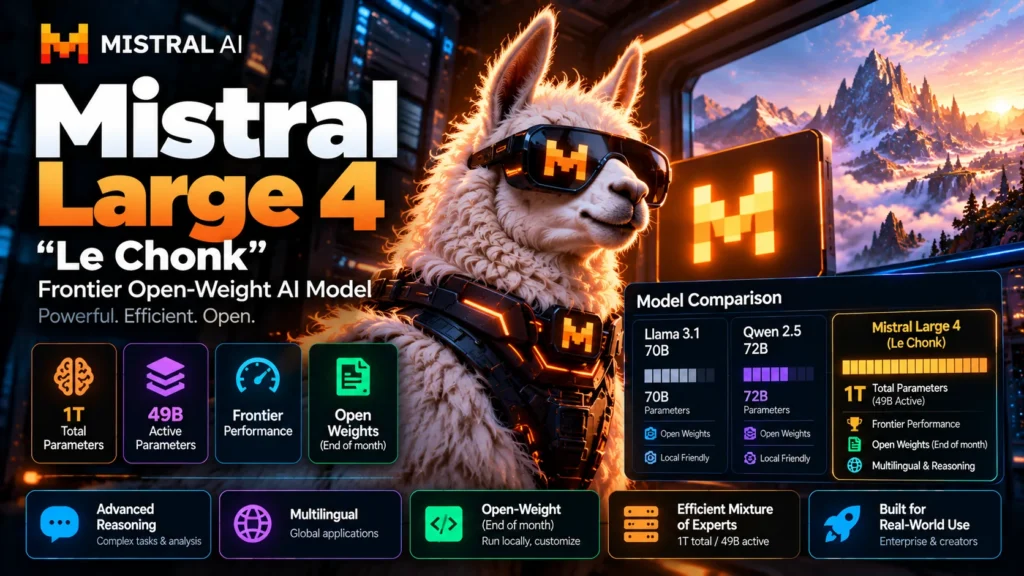
Updated October 31, 2026. Mistral Large 4 (Le Chonk) entered public preview on October 6, 2026, and its improved open weights were released on October 29, 2026. The earlier preview-only status is no longer current. Mistral describes Le Chonk as a natively multimodal mixture-of-experts model with approximately one trillion total parameters and 49 billion active parameters, supporting coding, reasoning, visual understanding and defensive cybersecurity.
Are Mistral Large 4 weights available?
Yes. The official checkpoints are available in FP8 and NVFP4 variants; the community also provides GGUF conversions through the llama.cpp and Unsloth ecosystems. See the Hugging Face release guide and official FP8 model repository. A downloadable model is not necessarily practical on a consumer desktop.
What changed after the October 6 preview?
Mistral continued reinforcement learning before publishing the October 29 weights. The company reports improvements in coding, reasoning efficiency and defensive cybersecurity, along with selectable low, medium and high reasoning effort. These are published vendor results; The Signal has not independently reproduced benchmark scores or inference speeds.
Model architecture and capabilities
Le Chonk combines sparse MoE computation with multimodal text-and-image input. Hugging Face documents approximately 1T total / 49B active parameters and a maximum context specification of 1 million tokens. Supported applications include coding agents, enterprise analysis, multilingual reasoning and vision-language tasks. The active-parameter count measures a computation path, not the amount of memory needed to load the full checkpoint.
How to run Mistral Large 4: FP8, NVFP4, GGUF and APIs
| Format / access | Best fit | Important limitation |
|---|---|---|
| FP8 official weights | Large multi-GPU infrastructure and supported inference stacks | Very large checkpoint; not a typical single-GPU setup |
| NVFP4 official weights | Supported NVIDIA hardware and optimized serving | Check hardware/runtime support; quantization is not universal |
| GGUF conversions | llama.cpp-compatible experimentation | Still an extremely large model; GGUF availability does not imply laptop feasibility |
| Mistral API / hosted endpoints | Developers without datacenter-class hardware | Usage fees and external processing apply |
Hugging Face documents inference support through Transformers, vLLM and llama.cpp. Its published managed deployment example uses eight NVIDIA H200 GPUs for FP8 serving; this is an example configuration, not a universal minimum for every quantization. Consult the official repository’s current README and hardware requirements before selecting an inference backend. Do not run unverified third-party installation scripts.
Can you run Le Chonk on a normal PC?
Not realistically as a straightforward desktop model on a typical 16GB-RAM computer or a small consumer GPU. Quantization reduces storage and potentially memory demand, but the model’s trillion-parameter scale remains a major deployment constraint. For practical smaller alternatives, see our open-source LLM deployment guide and local AI hardware overview.
License: open weights are not unrestricted open source
The checkpoint uses the Mistral Ecosystem Open-Weight License, a modified MIT-style license. Mistral states that the model may generally be used, modified, fine-tuned and commercialized, but businesses operating a Model-as-a-Service offering must obtain a separate commercial license. Review the official release and license link before commercial deployment. Do not label this checkpoint simply “Apache-2.0” or assume all hosted resale rights are granted.
Mistral Large 4 at a glance
| Attribute | Verified release information |
|---|---|
| Preview announced | October 6, 2026 |
| Open weights released | October 29, 2026 |
| Architecture | Multimodal mixture of experts |
| Parameters | About 1T total / 49B active |
| Published weight formats | FP8 and NVFP4; GGUF conversions available |
| Inference ecosystems | Transformers, vLLM, llama.cpp; hosted API |
| License | Mistral Ecosystem Open-Weight License |
Frequently asked questions
Is Mistral Large 4 available for download?
Yes. The official FP8 and NVFP4 checkpoints were published October 29, 2026, and GGUF conversions are also available.
Is it open source?
It is open-weight. Access to model weights is not the same as an unrestricted software-and-training-data release. The license has a separate commercial condition for Model-as-a-Service businesses.
Does 49B active mean I only need enough VRAM for a 49B model?
No. Active parameters describe sparse execution, not the full storage and memory footprint.
Did The Signal benchmark the model?
No. This article is based on official documentation and release information; no local performance, accuracy or GPU-memory test has been conducted.
Official sources
- Mistral AI: Mistral Large 4 open-weight release
- Hugging Face: Welcome Le Chonk (October 29, 2026)
- Mistral Large 4 FP8 model repository
Editorial note: Updated October 31 to replace outdated preview-only statements with the confirmed open-weight release. No inference benchmarks were performed by The Signal.