
MODELS
Generative AI models explained and tested: capabilities, benchmarks, hardware requirements, licensing and practical use.
Wan AI Video Models: Open Generation, Workflows, and Local Use
Wan AI video models explained from Wan 2.1 to Wan 2.2: text-to-video, image-to-video, ComfyUI, consumer-GPU options, MoE architecture and workflows.
LTX Video: Open AI Video Generation, Models, and ComfyUI Workflows
LTX Video and LTX-2 explained: synchronized audio-video generation, ComfyUI workflows, keyframes, controls, upscaling, hardware and local deployment.
Open Source LLMs: How to Choose, Run, and Deploy Local Language Models
Open-source and open-weight LLMs explained: model selection, quantization, local inference, hardware, APIs, licensing and practical deployment.
Open Source AI Image Generators: Models, Tools, and Local Workflows
Open-source AI image generators compared across FLUX, Stable Diffusion, editing, ComfyUI workflows, licensing, local hardware and practical use cases.
Open Source AI Video Generators: Models, Tools, and Local Workflows
Open-source AI video generators compared across text-to-video, image-to-video, ComfyUI workflows, hardware requirements, licensing and local deployment.
Open Source AI Models: A Practical Guide to Choosing and Running Them
Open-source and open-weight AI models explained: licensing, LLMs, image and video generation, local deployment, hardware requirements and how to choose the right model.
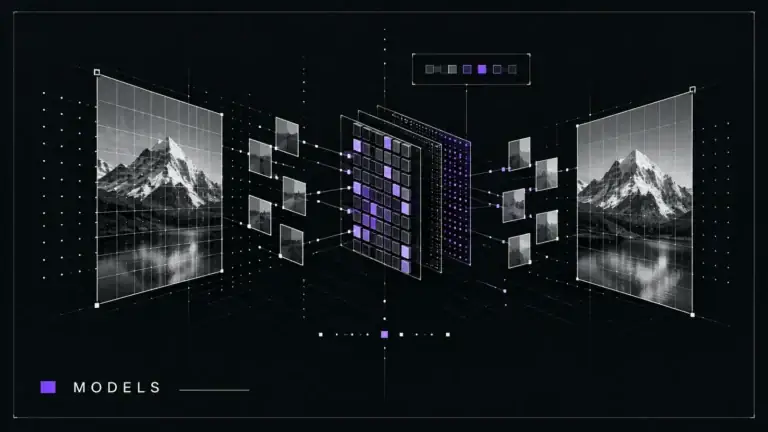
VTP: MiniMax’s Research on Scalable Visual Tokenizers
VTP explores scalable visual tokenizer pre-training for image generation, combining representation learning and reconstruction to improve generative model scaling. Code and weights available; license unverified.
HunyuanVideo-1.5: Tencent’s 8.3B Open Video Generation Model
HunyuanVideo-1.5 is an 8.3B-parameter text- and image-to-video model with training code, Diffusers and ComfyUI support. 14GB VRAM minimum. License unverified.
VideoCrafter: Tencent AI Lab’s Open Text- and Image-to-Video Toolbox
VideoCrafter is an open-source AI video generation toolbox with text-to-video and image-to-video models, inference scripts and a Gradio demo, including VideoCrafter1 and VideoCrafter2. License unverified.
Wan 3.0: Alibaba’s New AI Video Model
TL;DR: AI video is moving fast, and Alibaba clearly does not intend to watch from the sidelines. With Wan 3.0, […]