Open-source AI image generators give creators and developers more control than closed prompt-only services: you can run models locally, inspect the workflow, combine checkpoints with LoRAs and ControlNet-style guidance, automate generation, and in many cases fine-tune the system for a specific style or task.
But “open-source image generator” is not one uniform category. Some projects release code and weights under permissive licenses, while others are better described as open-weight because the model weights are downloadable but commercial or redistribution terms differ. VRAM requirements vary just as much — the same model can need anywhere from 15GB to 60GB+ depending on precision and optimization, which is often the deciding factor for who can actually run it.
What should you compare?
A practical image-model comparison should cover:
- prompt adherence and visual quality;
- text rendering;
- editing and inpainting;
- ControlNet or structural conditioning;
- LoRA and fine-tuning support;
- VRAM and inference speed;
- ComfyUI or Diffusers support;
- the exact code and model-weight licenses.
FLUX
Black Forest Labs publishes official inference code for its FLUX open-weight family. Its public catalog includes text-to-image, inpainting/outpainting, structural conditioning, image variation and image editing variants. The base model is a 12-billion-parameter rectified flow transformer, and the DiT (diffusion transformer) architecture behind it is meaningfully more memory-hungry than the older UNet-based Stable Diffusion designs — roughly double, for a comparable resolution.
Licensing differs by checkpoint. FLUX.1 [schnell] is listed under Apache 2.0, while several [dev] checkpoints use the FLUX.1-dev Non-Commercial License. That is a good example of why “FLUX is open” is not precise enough for commercial planning: the specific checkpoint matters.
| Checkpoint | Parameters | License | Typical role |
|---|---|---|---|
| FLUX.1 [schnell] | 12B | Apache 2.0 | Fast draft generation, 1-4 steps |
| FLUX.1 [dev] | 12B | Non-Commercial License | Highest-quality open FLUX output |
| FLUX.1 Kontext [dev] | 12B-class | Non-Commercial License | Instruction-based image editing |
| FLUX.1 Fill [dev] | 12B-class | Non-Commercial License | Inpainting and outpainting |
Independent GPU-speed testing (not run by Black Forest Labs) gives a rough sense of what each checkpoint costs in practice, at 1024×1024, batch size 1, FP16:
| GPU | Schnell (4 steps) | Dev (20 steps) |
|---|---|---|
| RTX 4090 (24GB) | ~2-4s | ~15-30s |
| RTX 3090 (24GB) | ~3-5s | ~20-35s |
| A100 80GB | ~2-4s | ~10-18s |
| H100 | ~1-2s | ~5-10s |
| L4 (24GB) | ~6-10s | ~35-60s |
The source for that table is explicit that these are approximate speeds that vary by software stack, sampler and system configuration — not a controlled first-party benchmark. Treat the numbers as a rough ordering of hardware tiers, not a guarantee.
Stable Diffusion
Stable Diffusion remains one of the most important open image-generation ecosystems because of its checkpoints, LoRAs, ControlNet integrations, fine-tuning tools and broad support across interfaces.
Stability AI currently uses a community-license structure for Stable Diffusion 3.5: free for research, non-commercial use, and commercial use by organizations or individuals under $1M in total annual revenue, with enterprise licensing required above that threshold. SD3.5 Large is an 8-billion-parameter Multimodal Diffusion Transformer (MMDiT) using three text encoders (OpenCLIP-ViT/G, CLIP-ViT/L and T5-XXL); SD3.5 Medium is a 2.5-billion-parameter variant built specifically to run on consumer hardware. As with FLUX, the exact model and license should be checked rather than assuming every Stable Diffusion release has identical terms.
Qwen-Image and the open Chinese-model wave
Alibaba’s Qwen-Image is a 20-billion-parameter diffusion model released under the Apache 2.0 license — a notably more permissive license than either FLUX [dev] or Stable Diffusion 3.5’s community terms. Its stated strength is text rendering inside generated images, including Chinese-language text, which has historically been a weak point for Western diffusion models.
Twenty billion parameters is large for a single-GPU image model, and it shows in the memory footprint. Third-party testing (again, not Alibaba’s own published figures) found Qwen-Image needs roughly 61.8GB of VRAM at FP16 for 1024×1024 generation — enough that a 24GB RTX 4090 fails outright at that precision. Quantizing to FP8 brings that down to roughly 24GB, which just barely fits a 4090; a 4-bit NF4 quantization brings it down further, to under 15GB, at some cost to output fidelity.
What actually decides whether a model fits your GPU
Parameter count alone is a poor predictor of VRAM needs, because precision and optimization technique change the footprint dramatically. A third-party benchmark compilation (methodology: vLLM-Omni framework, various resolutions) puts real numbers on that gap:
| Model | Configuration | VRAM required |
|---|---|---|
| SD3.5 Medium | 1024×1024 | ~20.1GB |
| SD3.5 Large | 1024×1024 | ~31.6GB |
| SD3.5 Large | 2048×2048 | ~45.5GB |
| FLUX.1-dev | 1024×1024, unoptimized | ~33.9GB |
| FLUX.1-dev | 1024×1024, quantized + CPU offload | <16GB |
| Qwen-Image | 1024×1024, FP16 | ~61.8GB |
| Qwen-Image | 1024×1024, FP8 | ~24.0GB |
| Qwen-Image | 1024×1024, NF4 4-bit | ~14.9GB |
The pattern holds across every model in the table: unoptimized FP16 weights roughly double the memory cost of an FP8 quantization, and 4-bit quantization can cut the footprint by 4x or more relative to full precision — at the cost of some inference speed (CPU offloading in particular trades VRAM for latency) and, at the more aggressive quantization levels, some output quality. “Fits in VRAM” and “recommended for production” are not the same claim, and most of these figures represent the former, not the latter.
Image generation vs image editing
Modern open image systems increasingly combine generation and editing. A useful workflow may include:
- text-to-image generation;
- inpainting and outpainting;
- reference-image conditioning;
- depth, edge or pose control;
- style or identity LoRAs;
- upscaling and restoration;
- instruction-based image editing.
For example, FLUX.1 Kontext [dev] is an open-weight image-editing model, while FLUX.1 Fill [dev] focuses on inpainting and outpainting.
Why ComfyUI matters
ComfyUI turns image generation into a reusable node graph. Instead of hiding the pipeline, it lets you connect model loading, prompts, samplers, control models, masks, LoRAs, upscalers and output stages directly.
This is especially useful for production work where the same visual process must be repeated with different inputs. It also makes it easier to compare models using the same surrounding workflow — the same node graph, swapping only the checkpoint, is a fairer comparison than two different tools with different defaults. The same node-graph logic extends to video generation; see our guide to ComfyUI video workflows for how the pattern carries over to Wan and other video models.
Local image generation
Running image models locally provides privacy, reproducibility and control over model versions. Hardware requirements vary widely: older or smaller diffusion models can run on modest GPUs, while newer architectures may require more VRAM or benefit from lower-precision and offloading techniques — see the VRAM table above for how much that gap actually is.
The most useful hardware question is not “what is the parameter count?” but “can this exact workflow run at my target resolution and batch size without constant offloading or out-of-memory errors?” Our broader local AI hardware guide covers GPU tiers and cost-per-token tradeoffs in more depth for readers weighing a hardware purchase.
Open creative canvases
Not every user wants to build a graph manually. Projects such as Jaaz place a more conventional creative canvas on top of local ComfyUI or cloud models. That gives non-technical users a simpler interface while keeping an open/local generation backend available.
Research beyond basic text-to-image
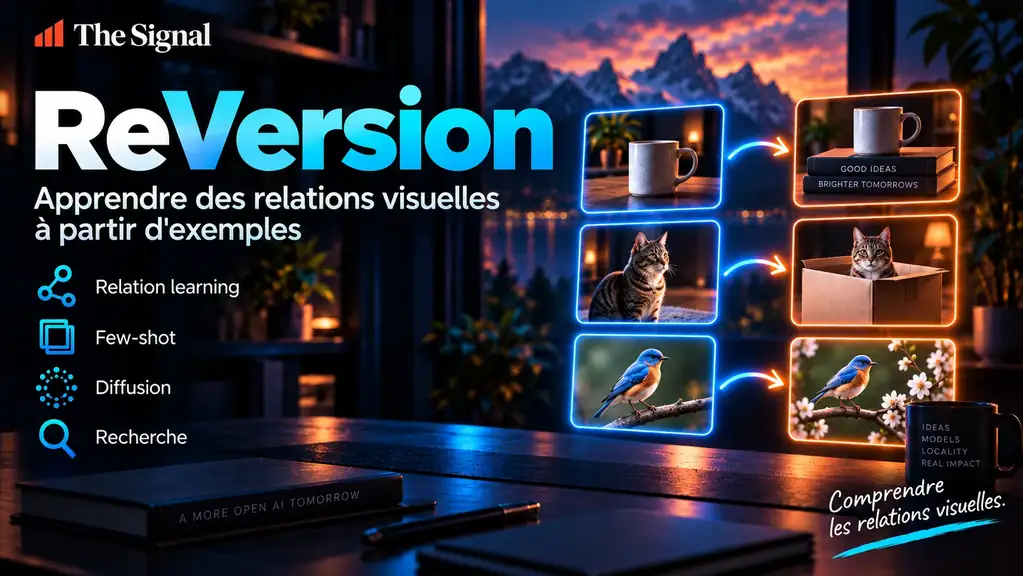
Open image research also includes projects such as ReVersion, which learns visual relations from examples, and VTP, which explores scalable visual-tokenizer pretraining for image generation.
How to choose
- Define whether you need generation, editing or both.
- Check the exact model-weight license.
- Confirm your hardware can run the target resolution — check VRAM at the precision you’ll actually use, not the FP16 headline figure.
- Verify ComfyUI, Diffusers or API support.
- Check whether LoRAs, ControlNet-style guidance or fine-tuning are available.
- Test your real use case rather than relying only on curated examples.
About the figures in this article
The Signal did not run the VRAM or generation-speed benchmarks cited above. They come from third-party testing published by the sources listed below, and we’ve noted the stated test conditions (resolution, precision, framework) alongside each figure where the source specified them. Independent benchmarks for fast-moving open-weight models can disagree with each other and with a given model’s official documentation — for instance, a single source’s own FP16 generation-time figures for Qwen-Image were measured under conditions that its own VRAM table suggests wouldn’t fit an RTX 4090 at that precision, which is the kind of inconsistency worth flagging rather than smoothing over. Treat every number here as a directional estimate, and confirm on your own hardware before making a purchasing decision.
Sources
- Black Forest Labs — FLUX.1 [dev] official model card
- Black Forest Labs — FLUX.1-dev on Hugging Face
- Stability AI — Stable Diffusion 3.5 Large model card
- Alibaba Qwen Team — Qwen-Image model card
- Jarvislabs — FLUX GPU speed and VRAM comparison
- WillItRunAI — Qwen-Image VRAM and generation-time testing
- AceCloud — AI image and video model VRAM requirements (2026)
- Stability AI licensing
- ComfyUI official documentation