IMAGE
AI image generation and editing: open models, tools, workflows, comparisons and practical implementation.
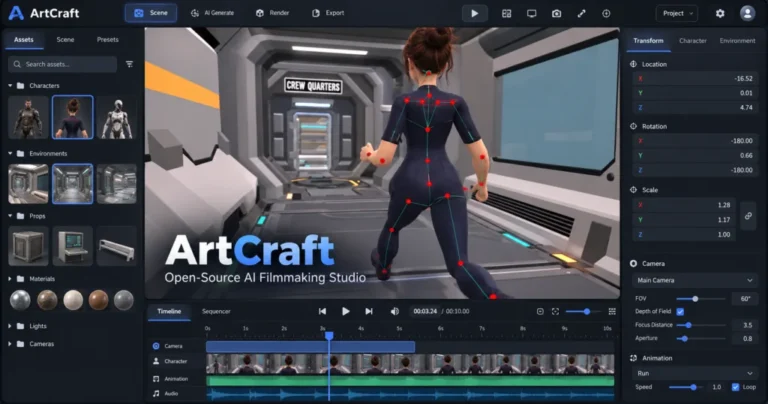
ArtCraft: Open-Source AI Filmmaking Studio for 2D, 3D and Video
ArtCraft brings 2D/3D scene control to AI filmmaking. Explore its GitHub features, model support, open-source license, costs, and ComfyUI comparison.
Open Source AI Image Generators: Models, Tools, and Local Workflows
Open-source AI image generators compared across FLUX, Stable Diffusion, editing, ComfyUI workflows, licensing, local hardware and practical use cases.
Jaaz: Source-Available Canvas for AI Images and Video
Jaaz connects an AI creative canvas to local models and cloud APIs. Explore setup options and its custom license restrictions on modification and team use.
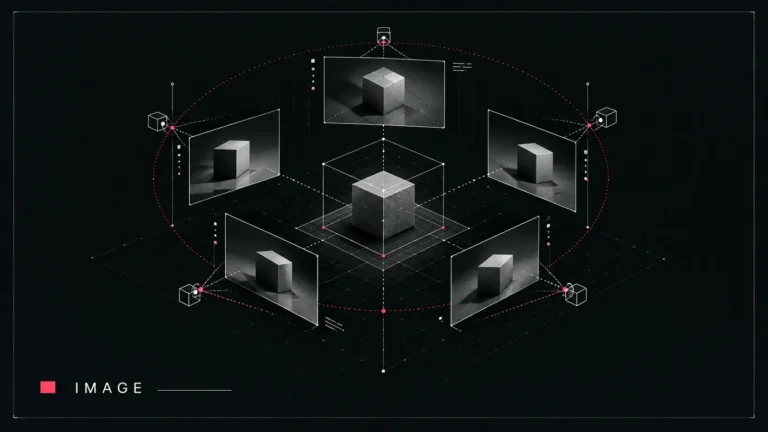
Stable Virtual Camera: Stability AI’s Model for New Camera Angles
Stable Virtual Camera is a 1.3B diffusion model for novel view synthesis, generating 3D-consistent camera views from one or more input images with controllable target cameras. License: Stability AI Non-Commercial License.
ReVersion: Teaching Diffusion Models a Relation From Examples
ReVersion is a diffusion-based relation inversion method that learns visual relationships from a few example images and applies the learned relation to new subjects and scenes. License: S-Lab License 1.0; non-commercial.
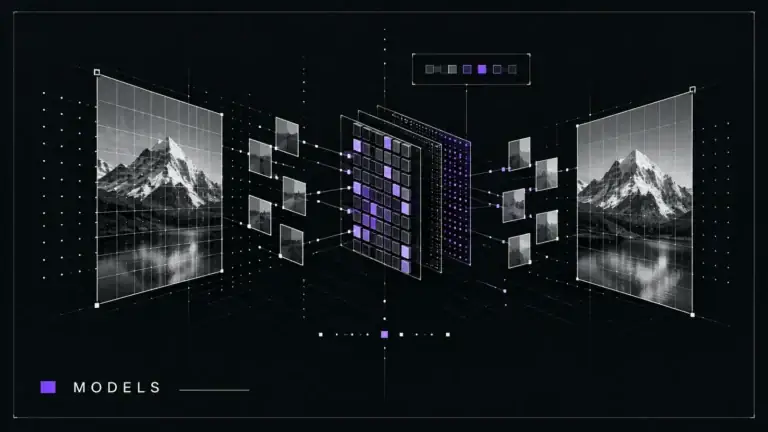
VTP: MiniMax’s Research on Scalable Visual Tokenizers
VTP explores scalable visual tokenizer pre-training for image generation, combining representation learning and reconstruction to improve generative model scaling. Code and weights available; License: MIT (repository software).
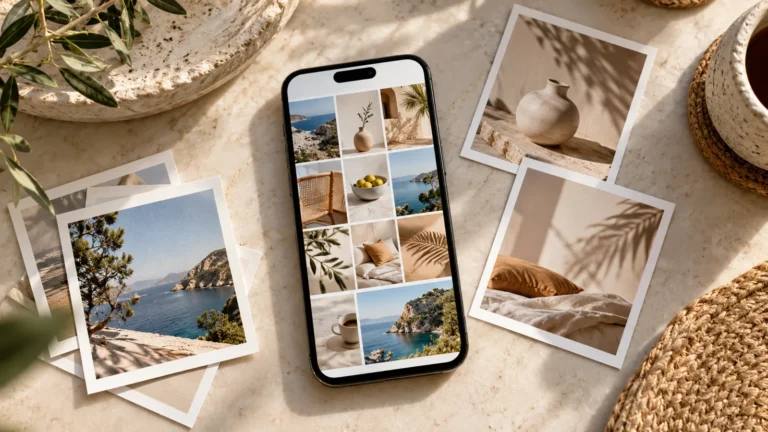
RedInk: Self-Hosted Generator for Xiaohongshu Image Posts
RedInk turns one sentence into a multi-page Xiaohongshu-style image post using Gemini and Nano Banana Pro via your own API keys. Docker install. License: CC BY-NC-SA 4.0; separate commercial authorization.
PromptEnhancer: Tencent Hunyuan’s Prompt Rewriter for Image Models
Tencent Hunyuan PromptEnhancer rewrites image prompts. Explore model options, setup, memory guidance and its custom license restrictions.
DeepSeek Ships an Experimental Vision Model, Claims It Rivals Opus 4.8 on Agent Tasks
DeepSeek quietly released DeepSeek-V4-Flash-Vision-Exp, a multimodal variant the company says closes the gap with Anthropic's Opus 4.8 on agent benchmarks that require visual understanding.