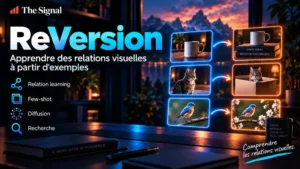
Most personalisation techniques for image models teach them a new object or style. ReVersion, from MMLab at Nanyang Technological University, targets something harder to describe in words: the relation between things. Show it a handful of images where one thing is “painted on” another, and it learns a prompt token for that relationship that you can reuse with entirely different subjects.
| Repository | ziqihuangg/ReVersion |
| Maintainer | Ziqi Huang (MMLab@NTU, S-Lab) |
| Primary language | Python |
| GitHub stars | 503 (as of 15 September 2026) |
| Last push | 7 October 2025 |
| License status | Unverified — see below |
What it does
The paper, presented at SIGGRAPH Asia 2024, introduces a task it calls Relation Inversion: given a few exemplar images that share a relation, find a relation prompt that captures that interaction, then apply it to new entities to synthesise new scenes. The repository contains:
- Training code to invert a relation from your own exemplar images plus short text descriptions.
- Inference code to generate images with a learned relation.
- The ReVersion Benchmark (example relation folders such as
painted_on) and pre-trained relation prompts, both linked from the README.
A March 2024 update means you only save and load the learned relation prompt, not a full copy of the text-to-image model.
Who it’s for
- Researchers working on controllable or compositional image generation.
- Practitioners comfortable with training scripts who want a relation-level concept, rather than an object-level one, for Stable Diffusion.
Getting started
The README’s setup creates a Conda environment with Python 3.8, PyTorch 1.11.0, torchvision 0.12.0 and CUDA toolkit 11.3, then installs diffusers and the repository requirements. Training is launched with accelerate launch using a single-GPU config, and the example uses runwayml/stable-diffusion-v1-5 as the base model with 3,000 training steps. Each relation needs a folder of exemplar images (the benchmark uses ten) plus a text.json of coarse descriptions. The README does not state minimum GPU memory.
License status
Unverified. GitHub could not match this project’s license file to a standard open-source license (it reports NOASSERTION). The Signal has not reviewed the terms. Read the license file before any commercial use, redistribution or derivative work, and check the terms of the Stable Diffusion base model you pair it with.
Limitations and open questions
- The pinned environment (Python 3.8, PyTorch 1.11, CUDA 11.3) is several years old and may clash with current drivers and libraries.
- It is built on Stable Diffusion 1.5; the README does not mention newer base models.
- Research code first: expect to run scripts, not a polished app.
- We have not trained or run ReVersion ourselves.
Sources
- GitHub repository and README
- License file
- Paper: ReVersion: Diffusion-Based Relation Inversion from Images (arXiv 2303.13495)
- Project page
Related: Research · Stable Virtual Camera, another research release you can run locally.
This profile was drafted with AI assistance from the project’s public repository and reviewed by The Signal’s editors before publication. See our AI Disclosure.