LOCAL AI
Run AI locally: local inference, desktop tools, self-hosted servers, hardware requirements and deployment guides.
Nemotron 3.5 Transcribe: Local Setup, Multilingual ASR & Speaker Diarization
Set up NVIDIA Nemotron 3.5 Transcribe with NeMo Speech and vLLM, understand GPU requirements, multilingual ASR, diarization, translation and licensing.
GPU Unlock for RTX 30: Linux AI Benchmarks and Limits
GPU unlock boosts specific RTX 30 compute paths on Linux. Examine reported benchmarks, ComfyUI gains, LLM limits and card compatibility.
Granite Speech 5.0 Tutorial: Local Transcription, Setup & Whisper Comparison
Run IBM Granite Speech 5.0 locally for audio transcription and supported speech translation. Follow setup steps, hardware caveats and a fair Whisper comparison.
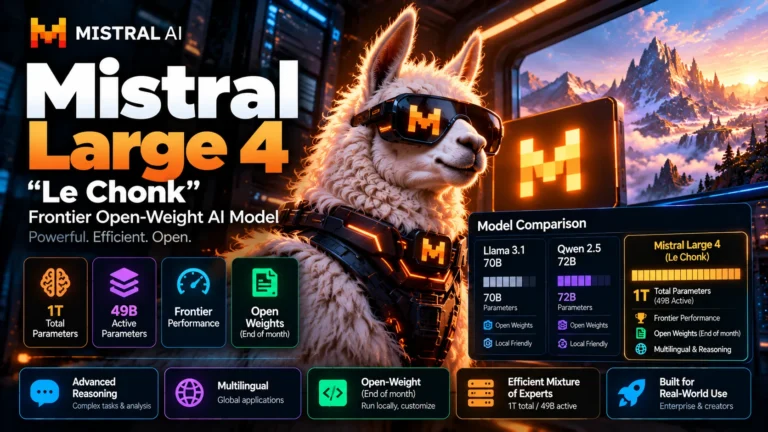
Mistral Large 4 Open Weights Released: FP8, NVFP4, GGUF & Local Hardware
Mistral Large 4 (Le Chonk) open weights arrived October 29, 2026. Compare FP8, NVFP4, GGUF, hardware needs, licensing and hosted alternatives.
Local AI: How to Run Generative AI on Your Own Hardware
Local AI explained: run LLMs, image and video models on your own hardware with private inference, self-hosted APIs, Apple Silicon and local workflows.
Open Source LLMs: How to Choose, Run, and Deploy Local Language Models
Open-source and open-weight LLMs explained: model selection, quantization, local inference, hardware, APIs, licensing and practical deployment.
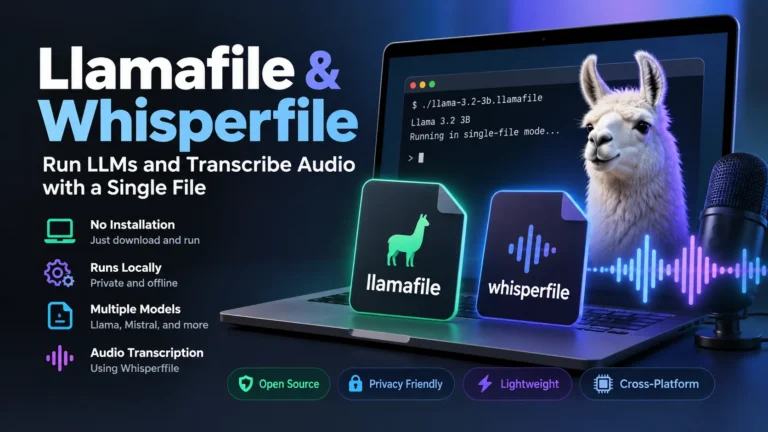
llamafile & Whisperfile: Run Local AI From a Single Executable
Run local AI with llamafile and speech-to-text with Whisperfile. Includes the current path for users searching for a whisper-tiny.en.llamafile download, setup guidance, portability, and local inference.
Rapid-MLX: A Local, OpenAI-Compatible AI Server for Apple Silicon
Rapid-MLX is a local AI server for Apple Silicon that runs LLMs on M-series Macs with OpenAI- and Anthropic-compatible APIs, CLI, desktop app and coding-agent support. License: Apache-2.0 (repository code).